LibreCrawl
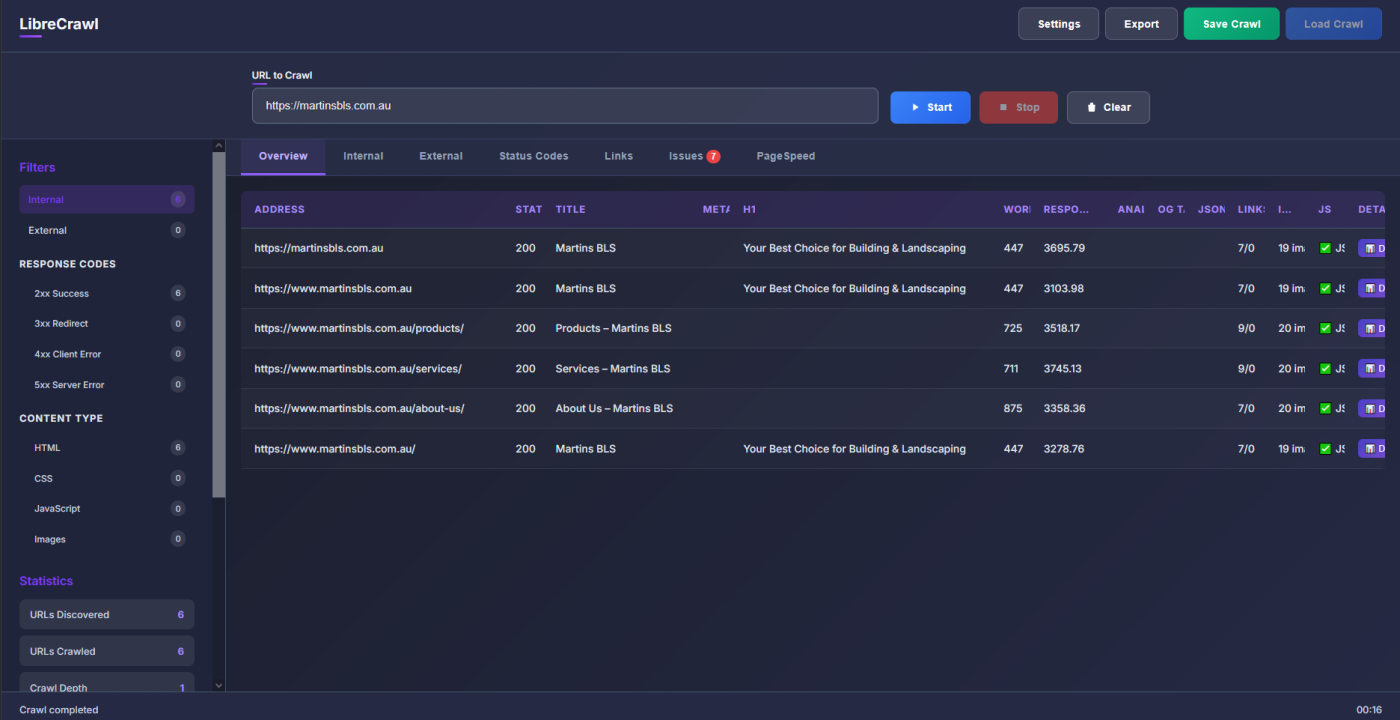
A self-hosted SEO crawler with a web interface, JavaScript rendering, internal and external link analysis, and exportable audit data.
Published Updated
What it does
- Metadata and link analysis
- JavaScript rendering for dynamic websites
- CSV, XLSX, JSON and XML exports
Requirements
- A compatible Python and browser environment
- Installation and dependencies from the project documentation
Running costs
The MIT-licensed crawler has no software subscription. You supply the host and browser resources; external integrations have separate terms.
Limitations
- The project describes a Flask web application; this listing does not assume a packaged desktop installer.
- A website crawl is not a commercial backlink index or a keyword-volume database.
Sources
Documentation and licensing references. This is a documentation review, not a hands-on benchmark.
Frequently asked questions
What is LibreCrawl used for?
Crawling websites to inspect links, metadata, structured data and technical SEO issues.
Can LibreCrawl render JavaScript?
Yes. It supports JavaScript rendering for pages that need a browser to load content.
Can I export LibreCrawl results?
Yes. Supported exports include CSV, Excel, JSON and XML.